scanpy.pp.calculate_qc_metrics#
- scanpy.pp.calculate_qc_metrics(adata, *, expr_type='counts', var_type='genes', qc_vars=(), percent_top=(50, 100, 200, 500), use=None, out=True (sc.settings.preset='scanpy-v1' – changes in 2.0), log1p=True, parallel=None, layer=None, use_raw=False, inplace=None)[source]#
Calculate quality control metrics.
Calculates a number of qc metrics for an AnnData object, see section
Returnsfor specifics. Largely based oncalculateQCMetricsfrom scater [McCarthy et al., 2017]. Currently is most efficient on a sparse CSR or dense matrix.Note that this method can take a while to compile on the first call. That result is then cached to disk to be used later.
Array type support# Array type
supported
… experimentally in dask
Array✅
✅
✅
✅
- Parameters:
- adata
AnnData Annotated data matrix.
- expr_type
str(default:'counts') Name of kind of values in X.
- var_type
str(default:'genes') The kind of thing the variables are.
- qc_vars
Collection[str] |str(default:()) Keys for boolean columns of
.varwhich identify variables you could want to control for (e.g. “ERCC” or “mito”).- percent_top
Collection[int] |None(default:(50, 100, 200, 500)) List of ranks (where genes are ranked by expression) at which the cumulative proportion of expression will be reported as a percentage. This can be used to assess library complexity. Ranks are considered 1-indexed, and if empty or None don’t calculate.
E.g.
percent_top=[50]finds cumulative proportion to the 50th most expressed gene.- use
LayerAcc|str|None(default:None) Which matrix to use for expression values. Given by an accessor, e.g.
A.XorA.layers['counts'].strs areanndata.acc.AdAcc.resolve()d, e.g.'layers.counts'.- layer
str|None(default:None) Deprecated since version 1.13.0: Use
useinstead.A key of
layers, i.e.layer='k'isuse=A.layers['k'].- use_raw
bool(default:False) Deprecated since version 1.13.0:
rawis deprecated. Keep the data in a layer instead.If True, use
adata.raw.Xfor expression values instead ofadata.X.- out
MultiAcc|str|QcMetricsOut|bool|Default(default:True (sc.settings.preset='scanpy-v1' – changes in 2.0)) Where to write the metrics. If
False, they are written as columns of.obsand.var(see below). An accessor likeA.obsm['qc']writes the metrics tables as wholeDataFrames to.obsm['qc']and.varm['qc']instead. A mapping writes only the tables it names, e.g.{'obs': A.obsm['qc']}.strs areanndata.acc.AdAcc.resolve()d. IfTrue, they are returned as aQcMetricsResultinstead of written. The default depends onscanpy.settings.preset:TrueforScanpyV1,FalseforScanpyV2Preview.- log1p
bool(default:True) Set to
Falseto skip computinglog1ptransformed annotations.- inplace
bool|None(default:None) Deprecated since version 1.13.0: Use
out=Falseinstead ofinplace=True.Whether to place calculated metrics in
adata’s.obsand.var.
- adata
- Return type:
- Returns:
Returns the calculated metrics (as
QcMetricsResult) ifout=True, elseNone. Without=False, sets the following columns ofadata.obsandadata.var(an accessor or mapping writes them as tables instead, seeout):Observation level metrics include:
total_{var_type}_by_{expr_type}E.g. “total_genes_by_counts”. Number of genes with positive counts in a cell.
total_{expr_type}E.g. “total_counts”. Total number of counts for a cell.
pct_{expr_type}_in_top_{n}_{var_type}– forninpercent_topE.g. “pct_counts_in_top_50_genes”. Cumulative percentage of counts for 50 most expressed genes in a cell.
total_{expr_type}_{qc_var}– forqc_varinqc_varsE.g. “total_counts_mito”. Total number of counts for variables in
qc_vars.pct_{expr_type}_{qc_var}– forqc_varinqc_varsE.g. “pct_counts_mito”. Proportion of total counts for a cell which are mitochondrial.
Variable level metrics include:
total_{expr_type}E.g. “total_counts”. Sum of counts for a gene.
mean_{expr_type}E.g. “mean_counts”. Mean expression over all cells.
n_cells_by_{expr_type}E.g. “n_cells_by_counts”. Number of cells this expression is measured in.
pct_dropout_by_{expr_type}E.g. “pct_dropout_by_counts”. Percentage of cells this feature does not appear in.
Example
Calculate qc metrics for visualization.
import scanpy as sc
import seaborn as sns

pbmc = sc.datasets.pbmc3k()
pbmc.var["mito"] = pbmc.var_names.str.startswith("MT-")
sc.pp.calculate_qc_metrics(pbmc, qc_vars=["mito"], out=False)
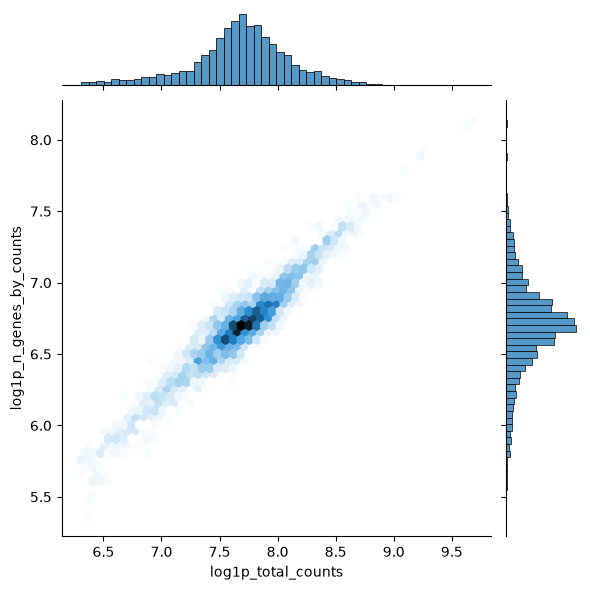
sns.jointplot(
    data=pbmc.obs,
    x="log1p_total_counts",
    y="log1p_n_genes_by_counts",
    kind="hex",
)
<seaborn.axisgrid.JointGrid at 0x706bcf5db8c0>
sns.histplot(pbmc.obs["pct_counts_mito"])
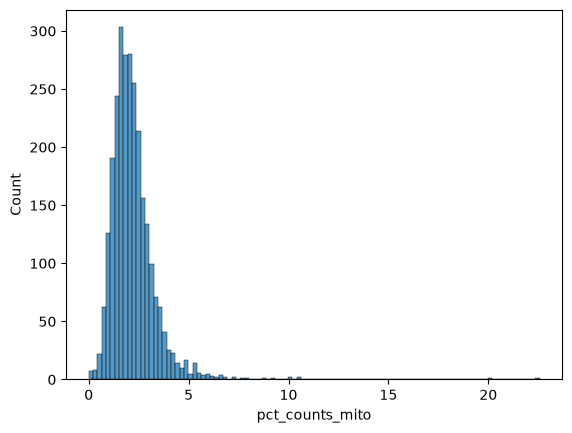
<Axes: xlabel='pct_counts_mito', ylabel='Count'>